Oral Stops, Vowel Formants, and Emphatic Consonants
An exploratory acoustic comparison of American English, Egyptian Arabic, and Najdi Arabic, combining voice onset time, vowel-space measurements, and emphasis effects.
Full-paper summary
The project examines how languages and varieties organize stop voicing, vowel quality, and pharyngealized “emphatic” consonants. It joins three small analyses: voice onset time (VOT) in American English and two Arabic varieties; long-vowel formants in Egyptian and Najdi Arabic; and the effect of emphatic consonants on neighboring vowels.
The study is deliberately exploratory. Its value is methodological: it demonstrates a reproducible workflow from controlled recordings through Praat measurements to visualization in R, while showing how familiar phonetic diagnostics distinguish languages, dialects, and coarticulatory environments.
Participants and measurements
Recordings were segmented and measured in Praat. R was used to compare stop categories and plot vowel spaces. Emphasis was tested by comparing vowel formants adjacent to plain and emphatic consonants on both sides of the consonant.
Results in context
- American English voiced stops had negative or near-zero VOT, whereas voiceless stops showed longer positive lag.
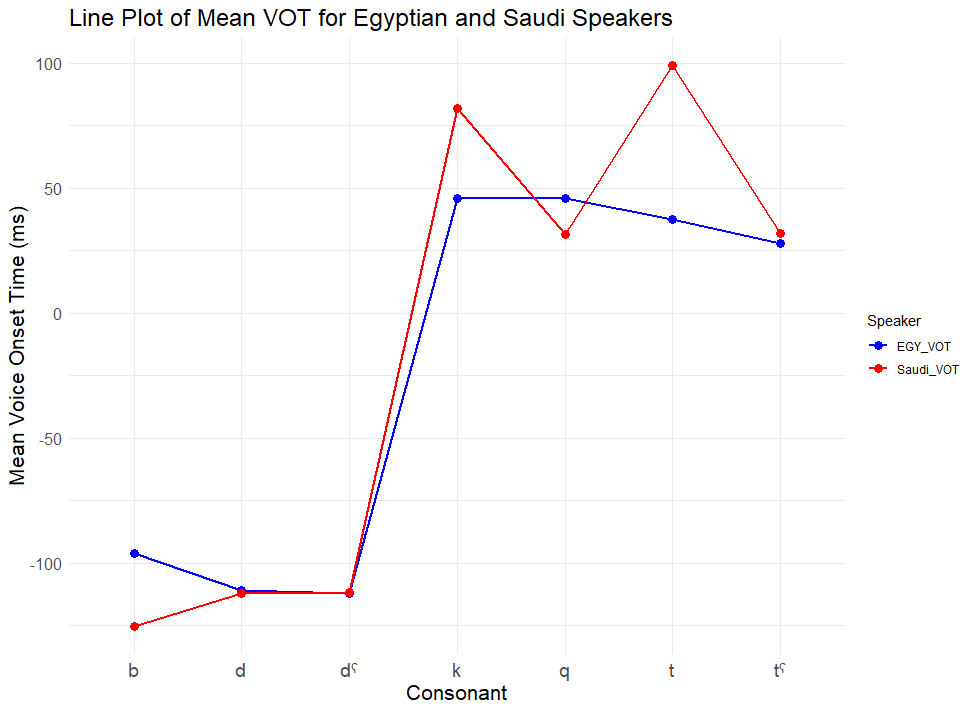
- Egyptian and Najdi Arabic also distinguished voiced from voiceless stops, with visible differences between the two speakers/varieties.
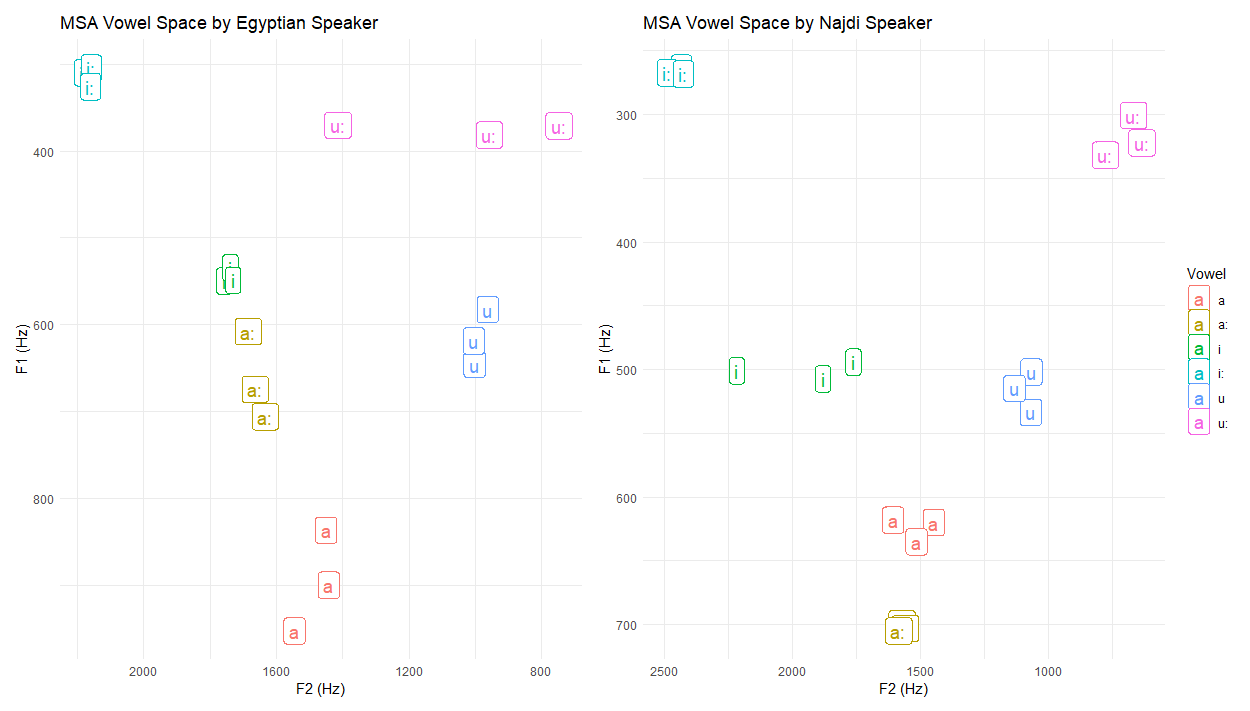
- The Egyptian speaker's long vowels were generally longer; the Najdi speaker's vowel space appeared more centralized in this sample.
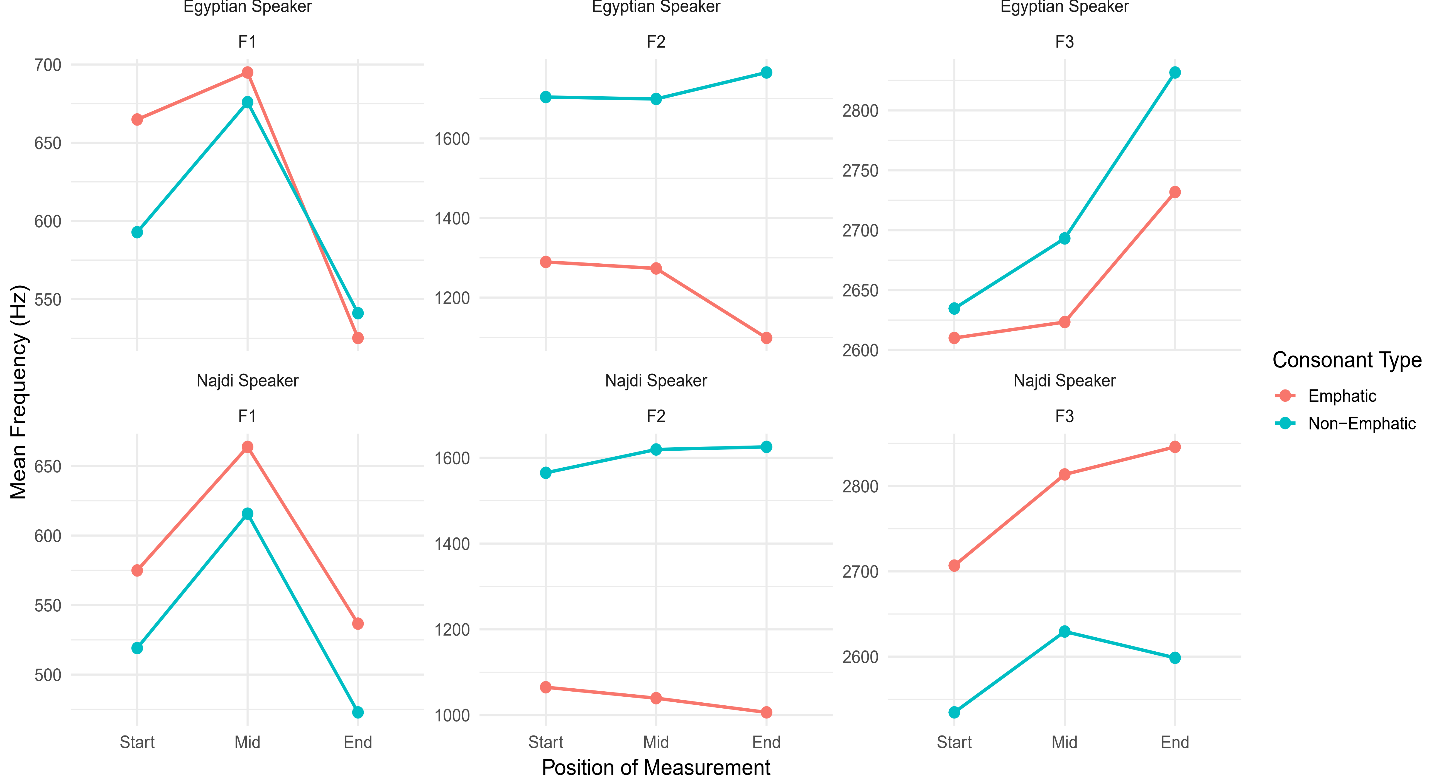
- Vowels next to emphatic consonants tended toward higher F1 and lower F2, consistent with a more open and retracted articulation.
- The emphasis effect appeared on both preceding and following vowels, supporting bidirectional coarticulation in the measured tokens.
Visualizations and commentary
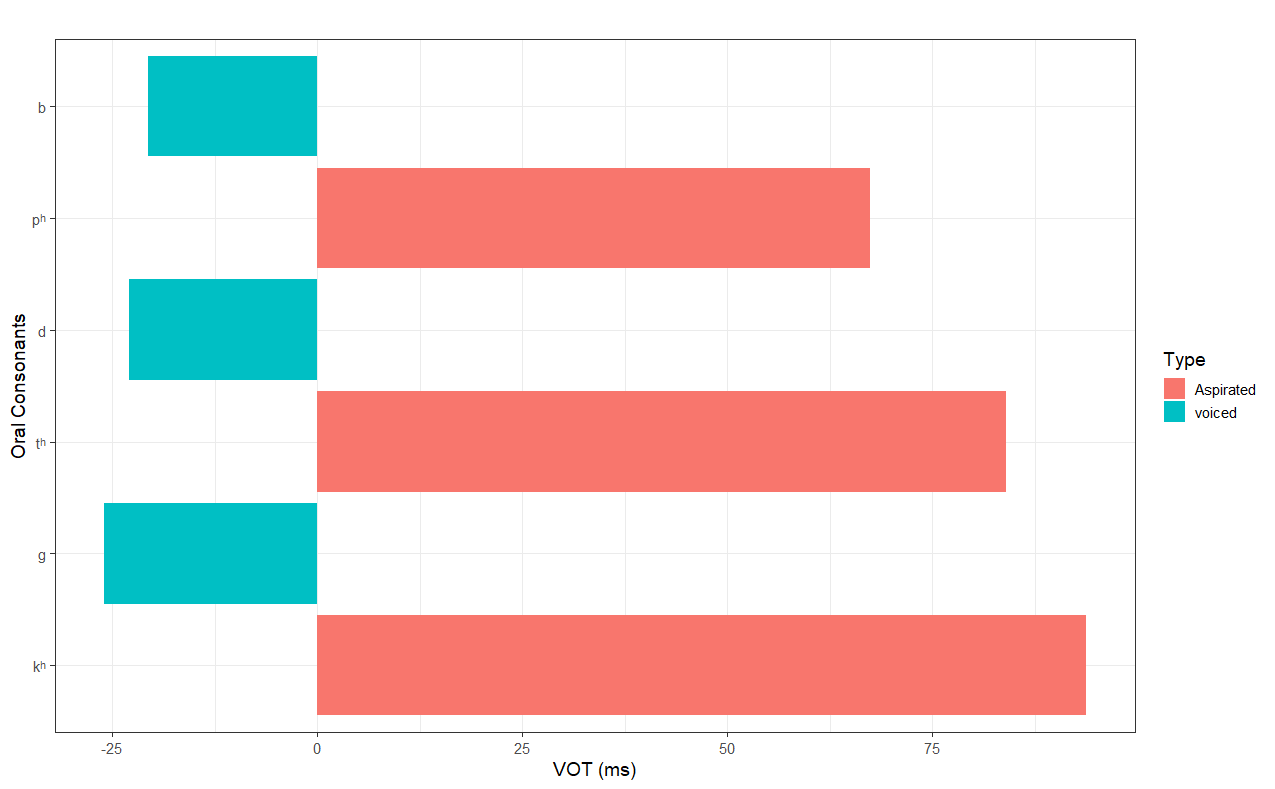
Limits and next steps
The principal limitation is the three-speaker convenience sample. Any difference may reflect an individual as much as a language or dialect. A confirmatory study should recruit multiple speakers across regions and genders, balance lexical items and phonetic environments, use carrier sentences, and model speaker and item variation statistically. The current results are best read as a technically grounded pilot that identifies measurable contrasts for that larger design.